
Qualitative research at scale: add 200+ in-depth interviews to your next survey
The same guide and 5–7 levels of laddering on every 20–30 minute conversation, with every theme counted and traced to who said it. 200+ panel interviews in 24 hours.

Walk me through the last time you made this choice. What tipped it?
The deciding reason surfaced four follow-ups deep, not in the first answer.
Trusted by teams at


A qualitative research platform is software for running and synthesizing in-depth, moderated interviews — historically forcing a tradeoff between depth and sample scale. User Intuition is a qualitative research platform powered by AI-moderated interviews, running 200-1,000+ in-depth conversations in parallel — each 20–30 minutes, probing 5-7 levels deep — and applying identical methodology to interview #1 and interview #1,000. Across 30K+ interviews run on User Intuition, depth stayed consistent from the first interview to the thousandth. Teams get qualitative richness with enough conversations to compare segments and count how often a theme appears, segmentable by cohort, geography, and behavior, and every conversation feeds a searchable intelligence hub. A User Intuition study starts at $150, returns evidence-traced qualitative results in 24 hours, and is backed by 4.9/5 on G2 and 5/5 on Capterra. The output is practical: depth at sample sizes large enough to compare segments, for insights, market research, and strategy teams replacing 12-interview qual studies.
What is a qualitative research platform at quant scale?
A qualitative research platform at quant scale runs hundreds of in-depth interviews in parallel without trading away depth. User Intuition's AI moderator holds 20–30 minute conversations that ladder 5–7 levels deep on every interview, 200+ panel interviews in 24 hours and 1,000+ per week. Recruit from a 4M+ vetted panel across 58 countries or bring your own sample, which runs in parallel as participants respond, with every theme counted and traced to the people who said it.
Who uses a qualitative research platform at this scale?
Research agencies adding hundreds of in-depth interviews to a client survey or tracker, and in-house insights teams that need segment-level qual stakeholders can act on.
How does AI-moderated qual at quant scale work?
Upload your guide and stimulus, then send respondents from your own survey through a link or recruit from the panel. The AI moderator runs every interview in voice, video or chat with the same laddering, and every finding links back to the recording.
What do you get from a qual-at-scale study?
Themes counted across hundreds of conversations, segment reads by cohort, geography or behavior, an editable presentation, and every transcript and recording.
Why can't qualitative research scale past a dozen interviews?
Qualitative research has run on an artisanal model for decades, and the limits are operational, not methodological. Here's what researchers tell us, and how User Intuition closes each gap.
- Sound familiar?
We're making a million-dollar call on twelve conversations.
1,000+ in-depth interviews per week
Run 200+ panel interviews in 24 hours and 1,000+ per week from a 4M+ vetted panel, with the same laddering on interview #1,000 as on #1, enough to compare segments and count how often a theme appears.
- Sound familiar?
Our survey shows which segment is slipping. Getting the why means a separate qual project weeks later.
In-depth interviews added to your survey
Send respondents straight from your survey into a 20–30 minute AI-moderated interview through a link, or recruit the same segment from the panel with hard quotas. Participants join on their own time, in 80+ languages, and every transcript and screener answer exports as CSV to analyze alongside your survey data.
- Sound familiar?
Our qual budget covers two projects a year, so most questions never get a single interview.
Pay only for interviews that pass
Traditional in-depth interviews cost up to $1,500 per IDI at full service (Drive Research, 2026 industry benchmark), billed regardless of quality. User Intuition interviews cost a fraction of that, every conversation is scored on length, depth and coverage, and only the ones that pass are billed, so the same budget covers far more questions.
- Sound familiar?
When qual can't scale, we fall back on surveys, and now bots are answering those.
Real-participant depth, not a survey with a follow-up box
3% of devices now complete 19% of all surveys, and AI bots pass survey quality checks 99.8% of the time. Every interview here ladders 5–7 levels with screened, real participants; The Synthetic Mirage in Market Research documents what synthetic outputs miss.
From Research Question to Qual at Scale in 4 Steps
Set your parameters, let the AI run hundreds of deep conversations, and get segmented results with every theme counted and traced to the people who said it.
Set Your Research Parameters
Define your audience, research questions, and target scale — 200, 500, or 1,000+ interviews. Select segmentation criteria (cohort, geography, behavior) and choose interview modality. Bring your own guide, or the AI builds the discussion guide automatically.
AI Runs Interviews Simultaneously
User Intuition conducts hundreds of 20–30 minute conversations in parallel — each probing 5-7 levels deep with structured laddering. Interview #500 gets identical rigor to Interview #1. No fatigue, no quality decay.
Quality Monitoring at Scale
Panelists are vetted and tracked longitudinally across studies, every session is screened for AI-generated or coached answers, and only interviews that pass Length, Depth, and Coverage checks are billed, at any volume.
Segmented Analysis, Every Theme Counted
Receive themes counted and traced to the people who said them — how many enterprise buyers cited pricing friction, with their verbatims, not 'some people mentioned pricing.' Segment by cohort, geography, or behavior with enough depth to act on every finding.
Built for Volume Without Sacrificing Rigor
Scale without losing structure, evidence, or the ability to act on what you find.
Structured Consumer Ontology
Every insight, emotion, need, and competitive mention is classified into a standard ontology — making findings queryable, comparable across studies, and machine-readable from day one.
Evidence-Traced Verbatim
Every claim, theme, and finding links directly to the participant verbatim that supports it. With 98% participant satisfaction, engagement quality stays high even at scale. No ungrounded assertions — click any insight and see exactly what was said, by whom, and in what context.
Quantified Themes
Every theme is counted and traced to the people who said it — how many participants cited pricing friction, and who, not "some people mentioned pricing." Teams prioritize with the count and the verbatims side by side.
Structured Output Formats
Export findings as PDF reports, presentation decks, or structured data feeds. Board-ready first drafts generated automatically, so your analysts spend their time on interpretation, not write-up.
Customer Intelligence Hub
Every conversation feeds a searchable, compounding knowledge base. Query past studies in plain language, surface cross-study patterns, and ensure nothing is lost when teams change or time passes.
How Does AI Maintain Qualitative Rigor at 1,000+ Interviews?
AI removes moderator variability — the single biggest quality risk in qualitative research at scale. Every conversation gets identical laddering methodology, whether you run 20 interviews or 2,000.
Why AI Maintains Rigor at Scale
- Identical laddering methodology for every interview
- No fatigue — Interview #1,000 is as rigorous as #1
- Every theme counted and traced to the people who said it
- Dynamic probing calibrated against research standards
- Every finding includes evidence trails and verbatim citations
- Methodology validated across 30,000+ AI-moderated interviews
What Makes This Different from 'AI Surveys'
- 20–30 minute adaptive conversations, not multiple-choice questions
- 5-7 level laddering, not 'rate on a scale of 1-5'
- Empathetic follow-up that adapts tone to each participant
- Structured consumer ontology turns narratives into machine-readable insight
- Every session screened for AI-generated or coached answers
- Results you can cite with confidence at board level
Research methodology validated across 30,000+ AI-moderated interviews.
Every Solution Benefits from Scale
See how teams apply qualitative depth across research challenges.
Win-Loss Analysis
Scale buyer interviews across won and lost deals.
→Churn & Retention
Interview churned customers at volume to find patterns.
→Consumer Insights
Deep-dive into purchase motivations across segments.
→UX Research
Test prototypes with hundreds of users, not dozens.
→Concept Testing
Validate concepts with qual depth at quant sample sizes.
→Shopper Insights
Map shopper missions across demographics and channels.
→Why researchers choose User Intuition
User Intuition is an AI-moderated interview platform that gives research teams and agencies the depth of a senior researcher at the scale of a survey, with vetted respondents, your own methodology and evidence you can trace to the verbatim. Quality is built in: a person vets every panelist by hand, every session is screened for fraud, and you pay only for interviews that pass.
Senior-researcher depth
The moderator ladders 5–7 levels deep by default, using Reynolds and Gutman's laddering method, so you hear the reasons behind the reasons.
Your methodology, run as written
Bring your discussion guide and frameworks. Required questions stay pinned in order, word for word if you need it, study rules keep the moderator inside your compliance lines, screeners and hard quotas fill every cell to plan, and you decide how far it probes.
Every finding traces to its source
Click any theme through to the verbatim, the transcript and the recording. Nothing in the deliverable you can’t defend.
Respondents you can stand behind
A 4M+ vetted panel across 58 countries: a person listens to every panelist's interviews before they're accepted, then every session is screened for AI-generated or coached answers and panelists are tracked across studies. Or bring your own: customer lists, your panel provider, or respondents straight from your survey.
Deliverables ready to present
Themes, verbatims and an editable presentation for every study, plus every transcript, recording and screener answer to export into your own tools. Put your own brand on them when you need to.
Survey scale, quality-only billing
200+ panel interviews in 24 hours, with no cap on parallel conversations. Each one is scored on length, depth and coverage, and you pay only for those that pass.
- Isolated workspaces
- Confidential stimulus
- Never used to train AI models
- GDPR & CCPA compliant
- SOC 2 Type II examination underway
- Security →
Qual at Quant Scale vs. Traditional Qual
vs. Quantitative Surveys
| Dimension | Qual at Quant Scale (User Intuition) | Traditional Qual | Quantitative Surveys |
|---|---|---|---|
| Sample size | 200–1,000+ per study | 8–12 per study | 1,000+ per study |
| Depth per response | 5–7 levels of structured laddering | 3–5 levels (varies by moderator) | Surface-level, no follow-up |
| Time to insights | 24 hours for panel studies | 6–12 weeks | 1–2 weeks |
| Cost (10 participants) | $300 with your own sample | $15K–$75K per project | $500–$2,000 |
| Follow-up probing | Dynamic, adaptive per response | Depends on moderator | None — static questions |
| Data quality | Vetted panel; every session screened for AI-generated answers | High (but small n) | Declining (bot contamination) |
| Segment comparison | Enough conversations to compare segments and count theme frequency | Low (too few for subgroups) | High on metrics, no 'why' |
| Richness of findings | Emotions, motivations, verbatim | Emotions, motivations, verbatim | Percentages, ratings, rankings |
| Languages supported | 80+ languages, native-language interviews | Limited to moderator's languages (typically 1–3) | Translation-dependent; semantic loss in open-text |
| Output deliverables | Verbatim transcripts + quantified themes + structured data feeds + searchable hub | PDF report per study (weeks of manual analyst write-up) | CSV export of closed-ended responses |
| Turnaround consistency | Same methodology at interview #1 and #1,000 — AI doesn't fatigue | Moderator variability + fatigue after 4–6 interviews a day | Consistent but only at surface depth |
Hear the interviews. See the presentation.
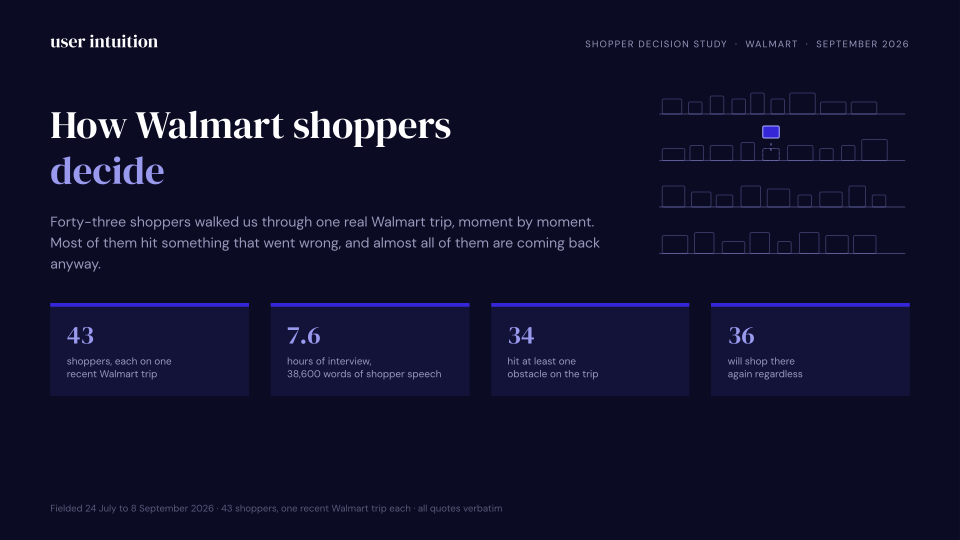
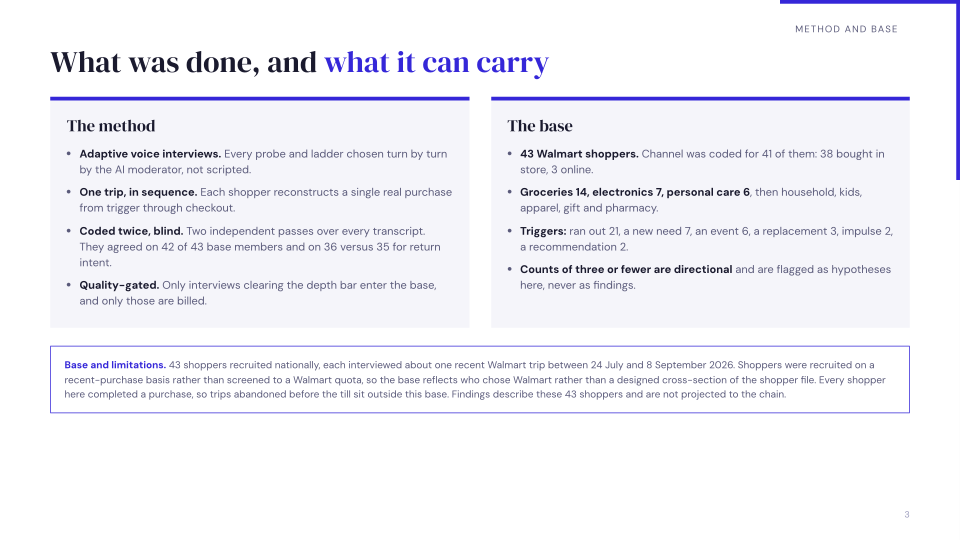
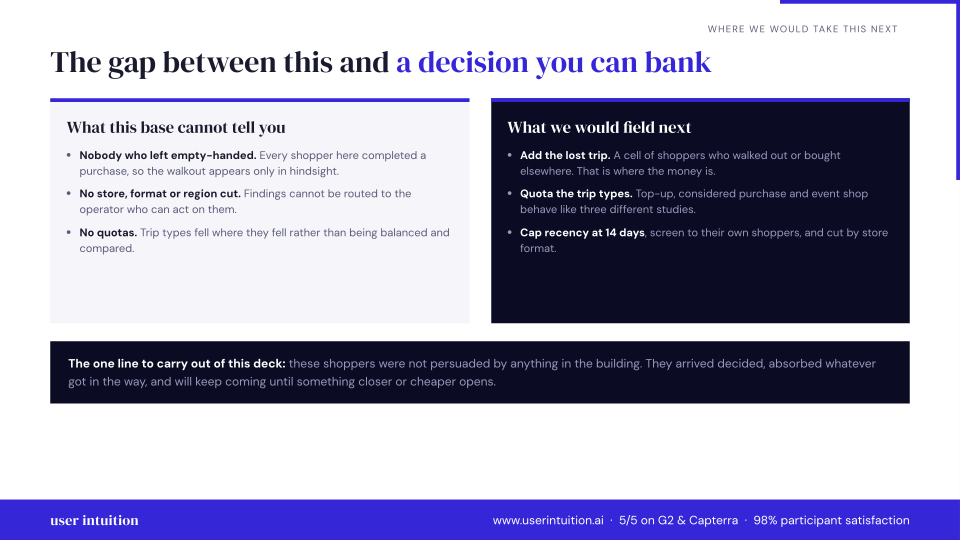
Explore calls and a sample presentation from our 43-participant Walmart shopper study.
Grocery top-up, supercenter
“Basically, because we use those things all a lot We try to always have you know, certain things in the house at all times because we use them very frequently. So we don't like to run out of them.”
What was making you want those specific things right then? Beyond just being out? Was it about being able to make certain meals or something else?
Basically, because we use those things all a lot We try to always have you know, certain things in the house at all times because we use them very frequently. So we don't like to run out of them.
Phone replacement, unplanned and urgent
“It made me feel so safe so relieved, and it brightened my day.”
Sounds like you knew exactly what you want. A Google Pixel 6 Pro. What was it about that phone that made it the right choice for you, especially in that moment?
Yeah. Thank you. So the the the phone had a lot of features. I I heard friends were talking about this phone. So in terms of the camera setting, it can take pictures and refine them into good quality. It has its own internal scanner, like I don't need to download other apps to scan to do scans. And of course, it has high quality for recording, which has been helping me in my meetings. In the office. So it's really amazing, and I love festival the quality of the phone in terms of the camera, because the previous phone I had was a Samsung. And the quality was really frustrating. And it had it has a very good processor speed as well. It's very fast. It's very efficient, and I like it. I like it. I'm enjoying the features.
Sample presentation
Preview three slides, or download the full 15-slide presentation.
Bring your own sample
$30 per quality voice interview
Use our 4M+ vetted panel
$60 per quality voice interview
What researchers say
"User Intuition gave us something we'd never had before — the ability to have hundreds of deep conversations with our consumers in days, not months, and actually use those insights to make decisions in real time. That's not incremental improvement. That's a fundamentally different way of building brands."
 Eric O., Chief Commercial Officer, Turning Point Brands
"We used User Intuition to conduct user research when people signed up for our product as part of the onboarding flow. This consisted of 50 interviews per week across different languages and countries: where the biggest drop-offs were and what people's initial reaction to our product was. It helped us understand where to streamline the onboarding flow."
Frequently Asked Questions
Run Your First Study at Scale
Book a demo to see hundreds of interviews in action, or start free with 3 interviews. Panel recruiting is billed separately.
From 3 interviews to 3,000. Same methodology. Same depth.
Related resources
Pillar Guides
Deep-dive guides covering this topic from strategy to execution.
Tools & Tactics
Practical frameworks and platform-specific guides for teams ready to act.
Reference Guides
Reference deep-dives on methodology, best practices, and applied research.
Alternatives & Comparisons
Side-by-side comparisons with competing platforms and approaches.
Related Solutions
Complementary research use cases that pair with this topic.
Last updated